
Xin Zhou
About Me
I am a second-year Ph.D. student at Huazhong University of Science and Technology, supervised by Prof. Xiang Bai and Dingkang Liang. My research focuses on 3D vision, particularly 3D understanding and generative models.
Current focus: foundation models, vision-language-action (VLA) models, world models, and world action models (WAM) for autonomous driving and embodied AI.
News
Scroll for earlier updates- [Sep. 2026] One paper is accepted to NeurIPS 2026.
- [Sep. 2026] Our work Qwen-Drive-1.0, a vision-language foundation model for driving, is released.
- [Sep. 2026] HERMES++ is accepted to TPAMI.
- [Jul. 2026] Selected as an Outstanding Reviewer for ECCV 2026.
- [Jun. 2026] One paper is accepted to ECCV 2026.
- [May. 2026] Recognized as a Silver Reviewer for ICML 2026.
- [Apr. 2026] Received an Excellence in Reviewing Award from Pattern Recognition.
- [Feb. 2026] Two papers are accepted to CVPR 2026.
- [Oct. 2025] Selected as the Top Reviewer at NeurIPS 2025.
- [Sep. 2025] One paper is accepted to NeurIPS 2025.
- [Jul. 2025] One paper is accepted to TPAMI 2025.
- [Jul. 2025] We release a training-free diffusion acceleration framework, now natively integrated into ComfyUI.
- [Jun. 2025] Finally achieve the bachelor's degree.
- [Jun. 2025] HERMES is accepted to ICCV 2025.
- [Apr. 2025] We win the 2nd place in the SoccerNet Monocular Depth Estimation Challenges (CVPR 2025).
- [Feb. 2025] One paper is accepted to CVPR 2025.
- [Sep. 2024] Two papers are accepted to NeurIPS 2024.
- [Sep. 2024] We win the 1st place in the FishNet Classification Challenge (ECCV 2024).
- [Apr. 2024] Invited to give a talk at FALML 2024.
- [Feb. 2024] One paper is accepted to CVPR 2024!
- [Jan. 2024] I will keep updating a collection of World Models 2,256 — check it out and give a star🌟!
- [Aug. 2023] One paper is accepted to PRCV 2023.
Selected Publications * Equal contribution
Full listVision(-Language)(-Action)
Vision-language(-action) foundation model pretraining for autonomous driving and embodied AI, plus unified generation and understanding.
-
 arXiv'26
A vision-language foundation model for driving that unifies 3D perception, driving VQA, and motion planning.
-
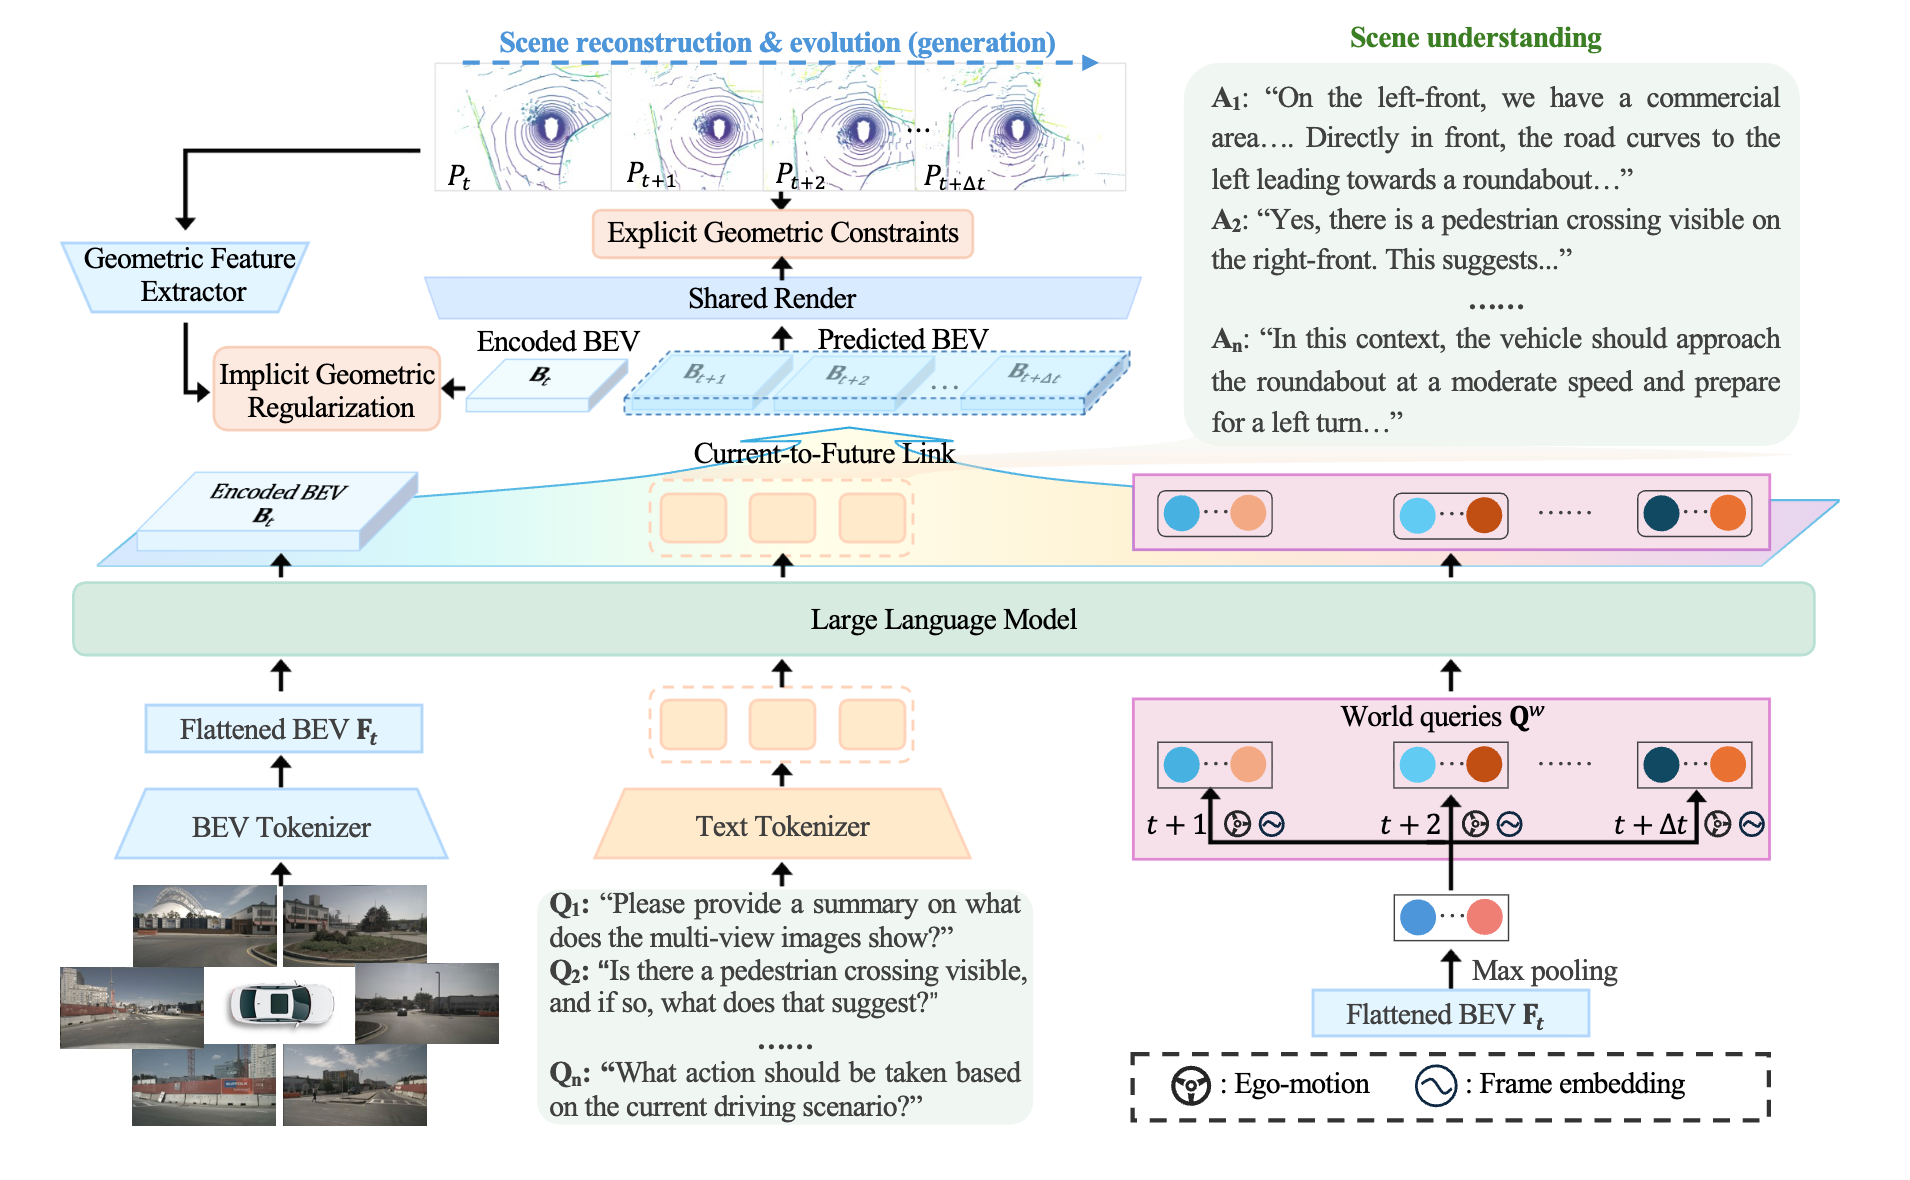 TPAMI'26/ICCV'25
ICCV 2025 version HERMES: A Unified Self-Driving World Model for Simultaneous 3D Scene Understanding and GenerationA unified driving world model enabling joint multi-view understanding and future lidar generation.
- arXiv'26 Qwen-VLA: Unifying Vision-Language-Action Modeling Across Tasks, Environments, and Robot Embodiments A unified vision-language-action model spanning tasks, environments, and robot embodiments.
- TIP'26 Extending Large Vision-Language Model for Diverse Interactive Tasks in Autonomous Driving Extends a large VLM from perception-level QA to diverse interactive driving tasks.
Generative World Model
Driving and general-purpose world models, world action models, and efficient video generation.
-
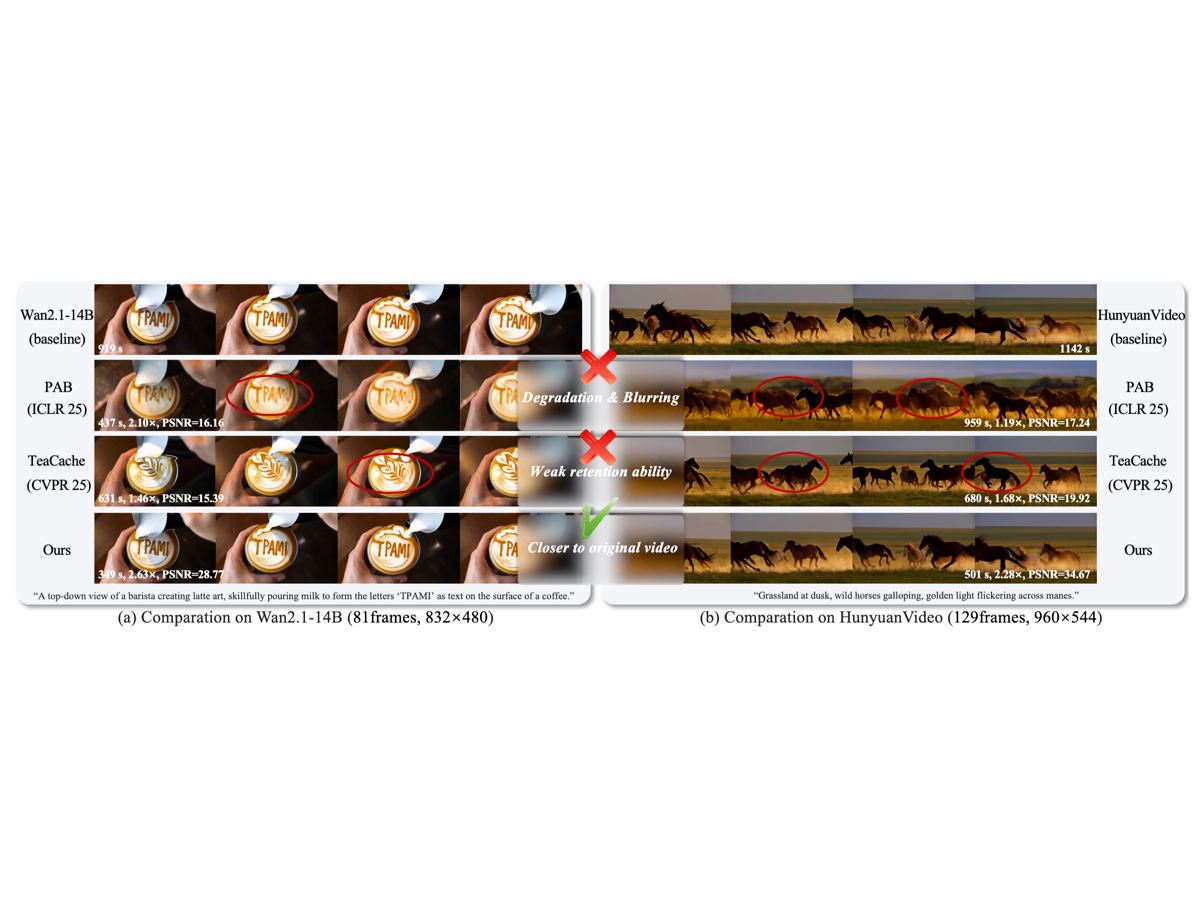 arXiv'25
Training-free video diffusion acceleration with runtime-adaptive caching. Officially integrated into ComfyUI; plug-and-play for Wan and MiniMax H3, etc.
- arXiv'26 SimWAM: A Simple World Action Model for End-to-End Autonomous Driving A simple world action model for end-to-end autonomous driving.
- ECCV'26 Divide and Conquer: Decoupled Representation Alignment for Multimodal World Models Decoupled representation alignment for multimodal world models.
- CVPR'26 When Numbers Speak: Aligning Textual Numerals and Visual Instances in Text-to-Video Diffusion Models Aligns textual numerals with visual instances in text-to-video diffusion.
- arXiv'26 Out of Sight but Not Out of Mind: Hybrid Memory for Dynamic Video World Models A hybrid memory mechanism for dynamic video world models.
- ICRA'26 UniFuture: A 4D Driving World Model for Future Generation and Perception A unified driving world model for future generation and future perception.
- FCS'26 A comprehensive survey of world models for autonomous driving.
3D Perception
Point cloud and 3D scene understanding.
-
 TPAMI'25
A spectral domain perspective for point PEFT, very strong performance.
 CVPR'24
 NeurIPS'24
- CVPR'26 PointTPA: Dynamic Network Parameter Adaptation for 3D Scene Understanding Dynamic test-time parameter adaptation for 3D scene understanding.
- NeurIPS'24 A Unified Framework for 3D Scene Understanding A unified framework for multi-task 3D scene understanding.
- PRCV'23 Diffusion-based 3D Object Detection with Random Boxes Diffusion-based 3D object detection trained with randomly sampled boxes.
Selected Experience
-
B.E., Huazhong University of Science and Technology (HUST)2021 – 2025
-
HUST Undergraduate Natural Science Innovation Fund Program2024 – 2025
-
National Undergraduate Training Projects for Innovation and Entrepreneurship2023 – 2025
- ¥20,000 (~$2,750) · Host · Rated Excellent2023 – 2024
- ¥10,000 (~$1,375) · Member · Rated Excellent2024 – 2025
-
Taihu Lake Innovation Fund for Future Technology2023 – 2025
Academic Service
- Conference Reviewer CVPR, ICCV, ECCV, NeurIPS, ICML, ICLR, AAAI, ICRA, WACV, ACCV
- Journal Reviewer TPAMI, IJCV, TNNLS, PR, RA-L, TMLR, SCIS, IJDE
- Reviewer Recognition Outstanding Reviewer, ECCV 2026 · Silver Reviewer, ICML 2026 · Excellence in Reviewing Award, Pattern Recognition 2026 · Top Reviewer, NeurIPS 2025
